Optimizing Local LLMs on Apple Silicon / EP04
SSD Expert Streaming: Running Large MoE Models with Less Memory
MoE experts can stay on SSD, but reads cost time. Routing, caches, prefetch and Apple Silicon support, before the Mac Studio arrives.
In this post
- Where does a model larger than 128GB go?
- MoE uses some experts; the others still exist
- Use it if present; read it if missing
- “SSD cache” can mean different data
- Less memory does not remove the wait
- Which Mac implementations would I investigate?
- 4-bit streaming or 3-bit residency?
- After delivery, start with a model that fits
- What I haven’t measured
Where does a model larger than 128GB go?
EP02 covered everything that needs memory besides model weights. EP03 explored ways to make a model generate faster once it fits.
This time the question comes earlier: what if the model does not fit in the first place?
The Mac Studio I ordered has 128GB of unified memory and a 1TB SSD. If one large model takes nearly all that memory, development tools and other AI models have little room. Buying another machine every time I want to try something larger is not much of a plan. Loading only the parts needed from SSD caught my attention.
SSD Expert Streaming. An appealing name, though it also means waiting for storage while generating an answer. The machine has not arrived. This is research into where memory and waiting go, not a report from a successful run.
MoE uses some experts; the others still exist
Unlike a dense model, a MoE has multiple experts in some layers. A router selects a subset based on its input. Switch Transformers is a representative study of selective execution. Some architectures also have shared experts or other common weights used every time.
Total parameters and active parameters describe different things: the whole model versus the part activated for a particular token. A smaller active count does not make the complete expert weight files smaller.
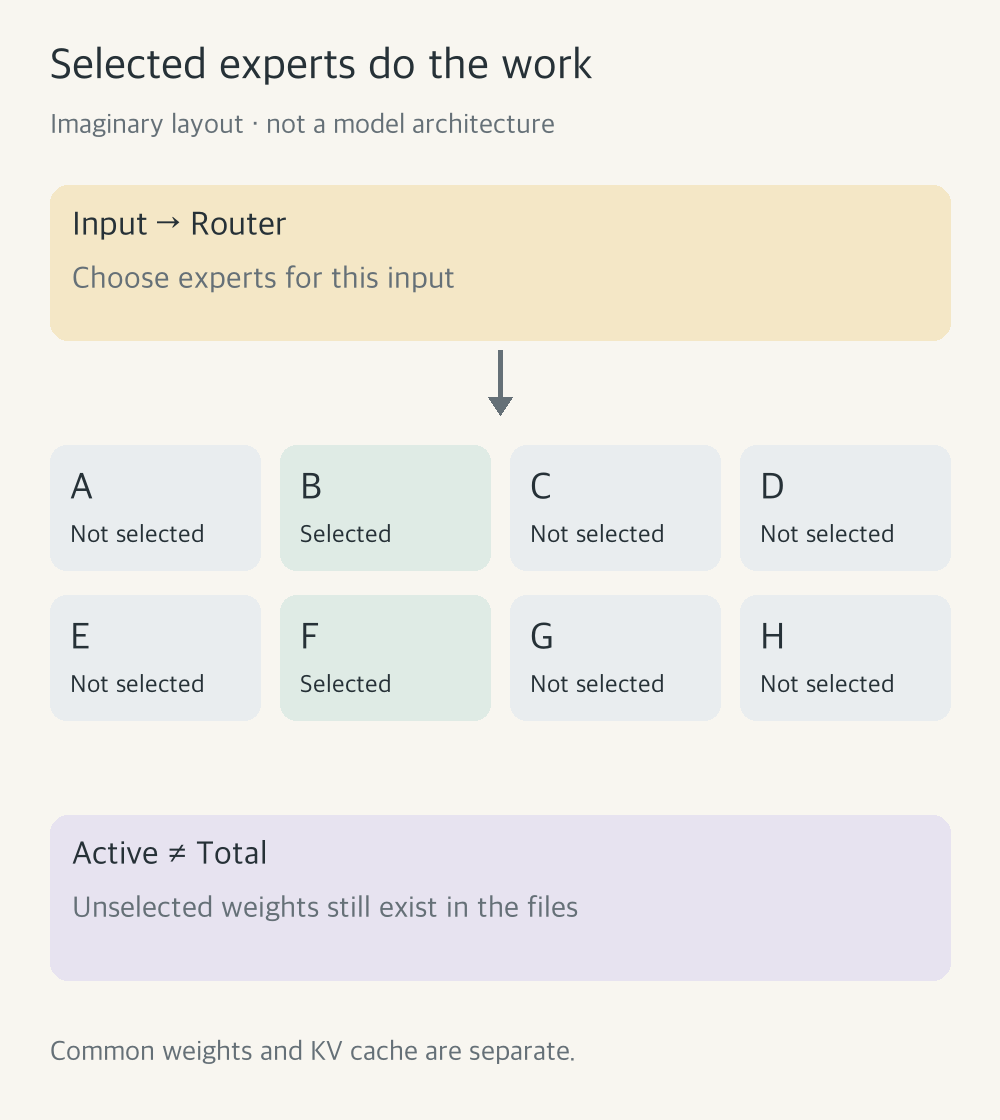
Instead of keeping every unselected expert in memory, an engine can leave weights on SSD and read them when needed. Computation does not happen on SSD. The retrieved weights go into execution buffers in memory, where the CPU or GPU uses them.
LLM in a flash also studies supplying weights from flash under memory constraints. Its techniques and every MoE engine’s expert streaming are not interchangeable implementations.
Use it if present; read it if missing
The basic flow is simple. The router selects experts, then the engine checks whether the required weights are in memory. Present means a cache hit; absent means a miss and a read from storage. An engine managing its own cache also decides what to evict when its budget fills up.
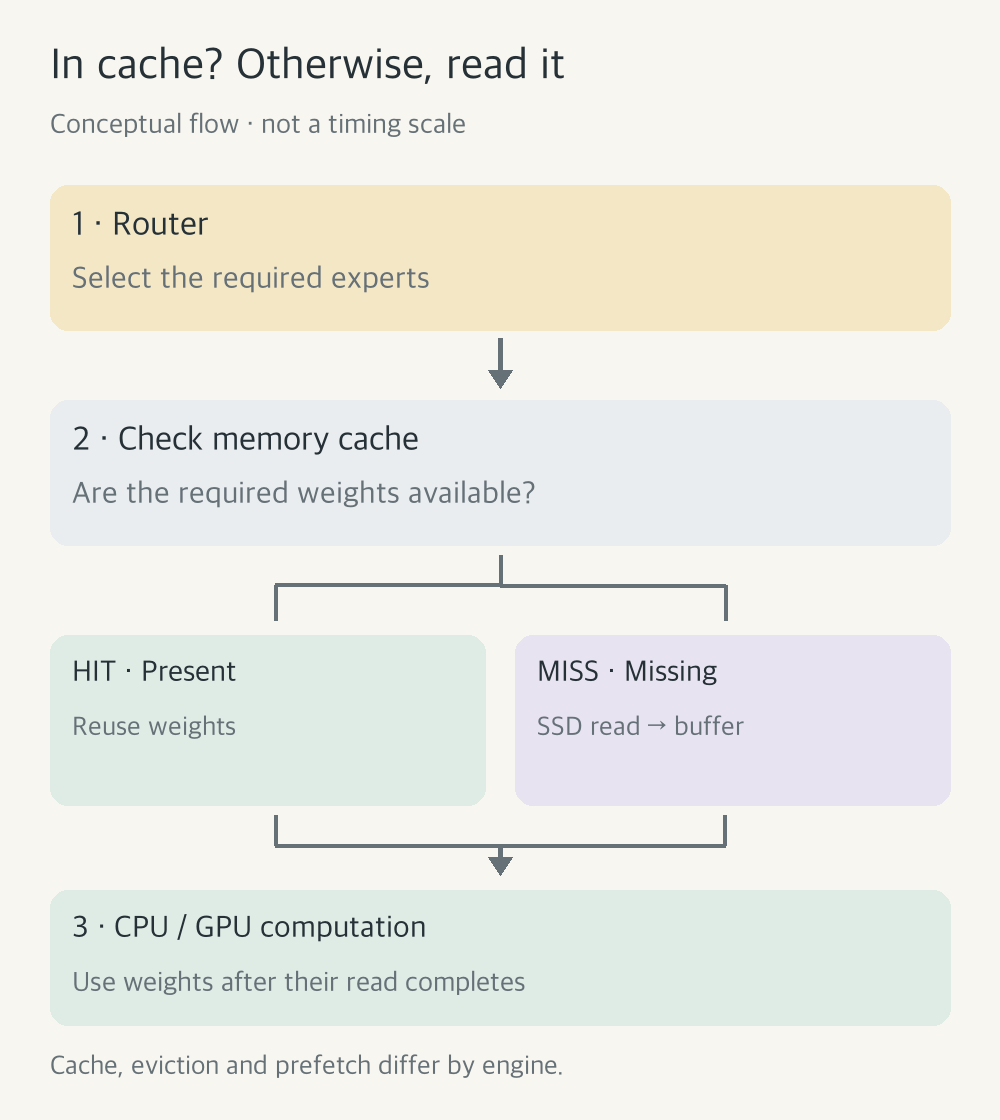
Suppose requests within one layer ask for A, B, then A again. The first A and B need loading; the third request can reuse A if it is still present. If it was evicted, that request misses too. This is an imaginary cache example, not a model execution result.
The flash-moe execution code contains router top-k selection, pread calls at selected expert offsets, completion checks and Metal-buffer use. It does not assume a read completed before using its data. Reading that path is different from reproducing it on my Mac.
“SSD cache” can mean different data
Several different mechanisms appeared under descriptions of SSD use.
| Mechanism | What goes on SSD | What it reduces or reuses |
|---|---|---|
| Expert weight streaming | Model expert weights | Need to keep all weights resident together |
| SSD KV cache | K/V state computed from earlier input | Work such as recomputing a matching prefix |
| System swap | Memory pages evicted by the OS | System-wide physical-memory pressure |
oMLX’s SSD tier documents saving KV-cache blocks and restoring them for a request with a matching prefix. That feature alone does not establish streaming of a large model’s expert weights. Separately, I checked its experimental MoE Expert Offload and weight-reading code. This path reads safetensors experts with os.pread into resident slots, but execution with my chosen model and feature combinations still needs verification.
mmap is another distinction. As Apple’s file-mapping documentation explains, mapping a file into virtual address space can let the kernel bring in pages as they are accessed. Mapping alone does not define an expert residency budget or read schedule. A streaming implementation may use mmap or the OS file cache, but the names do not describe the same feature.
Less memory does not remove the wait
I’m more curious about how often the required weights are read and how long those reads take than the maximum read speed listed in the SSD’s specifications.
Cache hits can avoid repeated reads. Expert sizes can vary, though, so identical hit rates need not mean identical bytes or waiting time. Reads served by the OS file cache and physical device reads need separate accounting too.
SNIA’s SSD performance overview starts with I/O size and workload. Maximum sequential bandwidth for large files differs from small random-read performance. Expert storage format, read granularity, alignment and request merging can all change the actual I/O pattern.
Queue depth counts outstanding requests. Concurrent requests may improve throughput, but the queue-depth/latency trade-off depends on the workload. I want to know whether the engine can issue reads early enough, and whether the GPU waits for a required expert. Higher QD alone does not establish faster token generation.
Temporal locality—reusing an expert soon—and spatial locality—nearby weights in a file—can affect cache efficiency. Correct predictive read-ahead, or prefetch, may hide waits; incorrect predictions add unnecessary I/O and cache pollution. Predicting reads without changing routing is different from changing the selected experts through an approximation. The latter also needs output-quality checks.
Multiple Hermes tasks sharing a model could change the access pattern. A wider expert working set might increase cache pressure, while expert reuse across requests might help. The relationship between concurrency and cache performance needs measurements.
SSD Expert Streaming cost calculator
Illustrative simulation · defaults are not measurements of a model or SSD. This calculator does not predict actual LLM tok/s.
- Total read volume
- MiB
- Data transfer cost
- ms
- Fixed latency cost
- ms
- Simplified SSD read cost
- ms
Data transfer cost Fixed latency cost
The bar shows the share of each cost, not a common time scale for comparing different inputs.
Formula and assumptions
read_MiB = expert_size_MiB × cache_misses
read_time_ms = (read_MiB / effective_bandwidth_MiB_s) × 1000
             + cache_misses × fixed_latency_ms
For read_bytes, multiply MiB by 2²⁰ and convert bandwidth to bytes/s too. Both volume and bandwidth here use MiB.
- Each cache miss causes one physical-device read request of the specified size.
- Reads do not overlap each other or GPU computation.
- OS file-cache hits and prefetch effects are excluded.
- Decompression, conversion, buffer allocation and GPU synchronization costs are excluded.
- Effective bandwidth is the attainable transfer rate for the I/O pattern; fixed latency is added as a per-request cost not already included in that transfer time.
Actual systems depend on request parallelism, I/O size, queue depth, OS file cache, expert locality, prefetch and GPU overlap. This is a simplified sequential, non-overlapping read cost, not predicted inference latency or actual latency per token.
Changing expert size and misses shows how modest individual reads can add up. The fixed latency here is a cost excluded from transfer time. If a measured effective bandwidth already includes whole-request latency, adding that latency again could double-count it. I need to establish what was measured before substituting real numbers.
Quantization can reduce weight bytes to read, but compatible kernels and dequantization work still matter. I will not assume reading, copying, dequantization and GPU computation always overlap neatly.
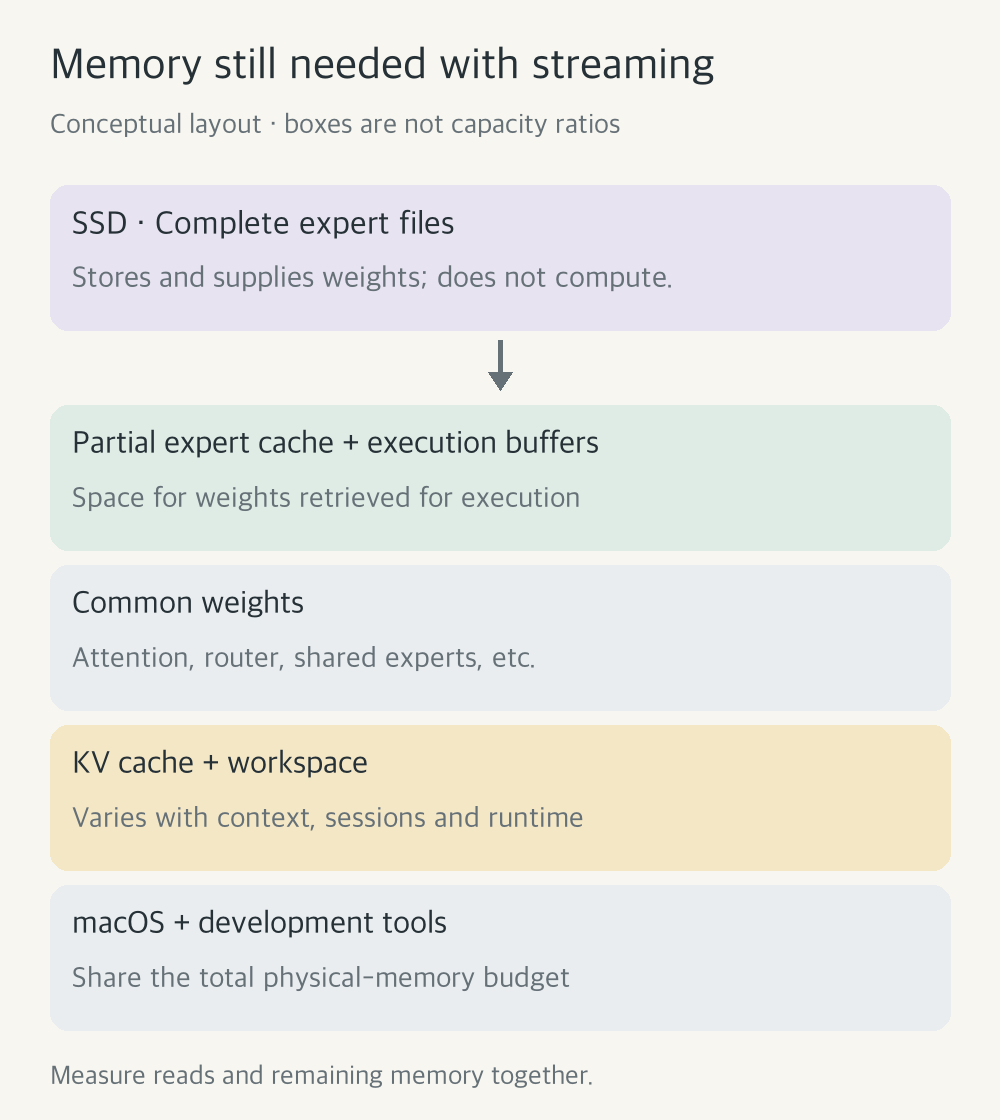
The expert cache belongs inside the EP02 memory budget. Longer contexts and more sessions need more KV state and other memory; common weights and execution workspace do not disappear. Putting weights on SSD does not finish the memory planning.
Which Mac implementations would I investigate?
The original source review was on October 9, 2026; additional code was checked on October 10. This is not a successful-installation list; links are pinned to inspected versions. Developer-published speeds are not predictions for my machine.
| Candidate | Inspected scope | Still to verify |
|---|---|---|
| ds4 | Documents bounded expert caching, GGUF reads and DeepSeek/GLM streaming on Metal | Exact model, tensor layout, effective cache budget and feature combination |
| Slipstream | Documents an Apple Silicon C++/Metal engine with expert streaming and read-ahead | Selected checkpoint’s loader, verification, cache path and actual execution unconfirmed |
| flash-moe | Model-specific Metal engine; source contains file reads after expert selection | Reproduction on my machine, converted files and quantization conditions |
| Strata-macOS | Metal execution for small GGUF models | Inspected README explicitly says original expert streaming and MTP are not wired to Metal |
The ds4 guide says other weights and context memory remain outside the expert cache budget. Its external DSpark documentation requires a resident main model and excludes SSD streaming. I cannot stack every EP03 optimization onto this configuration. That restriction should not be generalized to every other MTP path.
4-bit streaming or 3-bit residency?
Would I rather stream a large model’s 4-bit weights from SSD or fit its 3-bit version entirely in memory? Research such as GPTQ seeks to preserve quality at low bit widths, but bit width alone cannot establish quality loss on my tasks. Scales and other metadata, or mixed precision, can also affect total file size.
| What to check | 4-bit streaming | 3-bit resident |
|---|---|---|
| Quality and total weight size | Quantization format, actual files and evaluation results | Smaller files may be possible; check quality loss and metadata |
| Data supply and memory headroom | SSD I/O, expert-cache budget and remaining capacity | Bandwidth for resident weights and capacity freed by smaller weights |
| Decode and TTFT | Measure read waits, loading and kernels | Measure loading, memory reads and kernels |
| Long context and concurrent requests | KV cache, expert reuse and cache pressure | Whether KV cache and working space still fit |
Different quantization formats, runtimes or kernels make it hard to attribute differences to I/O or bit width alone, even within one model family. I will compare fixed-task quality with waiting time before choosing a winner.
After delivery, start with a model that fits
On the ordered Mac Studio M5 Max / 128GB unified memory / 1TB SSD, I will start with a supported model that fits in memory. If a larger model’s resident run is impossible, I will record “cannot run,” rather than calculate a slowdown against an invented baseline.
| Experiment | Comparison conditions |
|---|---|
| A · Resident vs Streaming | Same model, quantization and prompt where supported. Disclose any model or runtime difference |
| B · Expert Cache Sweep | 16GB → 24GB → 32GB → 40GB → 48GB is illustrative. Vary only within engine support and available mandatory headroom |
| C · Quantization Trade-off | Check support for the same model’s 4-bit streaming and 3-bit resident versions first; explore quality and speed evaluation on the same dataset |
| D · Internal vs External SSD | Internal SSD vs Samsung T7 with identical files, cache size, prompts and runtime. Add Thunderbolt NVMe or Samsung T9 if acquired later |
| What to record | Current status |
|---|---|
| Model load time, TTFT, prefill, decode tok/s and wall-clock response time | Measure after delivery |
| Peak memory, memory pressure and swap | Measure after delivery |
| SSD read bytes, I/O latency and expert-cache hits/misses | Check instrumentation, then measure |
| Requested bytes, physical-device reads, copies, dequantization and GPU intervals | Measure only what the runtime exposes |
| Output token count, stopping reason and fixed-task answers | Record alongside conditions |
I will hold model files, quantization, runtime version, prompts, input/output token counts, sampling, context and batch size fixed, changing either cache budget or storage at a time. Any mismatch will be disclosed beside the result. Bandwidth needs a separate measurement using the relevant read pattern; OS file-cache state, drive, connection interface, file system and thermal state need recording too.
Cold and warm runs will be separated, but restarting a process does not clear the OS file cache. Simulator inconvenience on my 8GB iMac with a 1TB external SSD does not establish expert-streaming performance. I will separate prefill, decode and total response time as in EP01.
What I haven’t measured
I do not know how well the cache will match my chosen large model or how much time reads will take. Even the 1TB internal SSD needs a storage budget if original weights, converted copies and development files share it.
I am interested in this because I do not plan to keep every large model resident. Everyday use would have a medium LLM and a small decision model, with larger models loaded when needed. Starting successfully and being tolerable to wait for remain different questions.
Which is more economical: using SSDs to cross a memory limit, or buying enough GPU memory from the start? EP05 — Mac Studio vs NVIDIA GPU: Building a Personal AI Workstation on the Same Budget will compare complete-system prices rather than GPU prices alone, alongside memory capacity, bandwidth, performance, power and expansion. I have not decided a winner before measurements.
Comments & likes
No account needed. Your nickname and comment will be public. Comments appear after review.