Optimizing Local LLMs on Apple Silicon / EP05
What if I had bought an RTX 5090 PC instead of a ₩8.6M Mac Studio?
I spent about ₩8.6M on a Mac Studio M5 Max 128GB. Comparing RTX PCs and DGX Spark helped clarify why my app development environment mattered alongside LLM speed.
In this post
₩8.6M — should I have bought an RTX PC?
I ordered a Mac Studio M5 Max with 128GB memory and a 1TB SSD. An education-discount route brought the payment to roughly ₩8.6M including AppleCare. AppleCare accounts for about ₩0.2M; the regular price for the same package was roughly ₩9.4M.
After paying, I started wondering about the alternatives. Would an RTX PC built with that money run local AI faster? I want to try big models and make images and video too. Was this a good purchase…?
But I am replacing more than an LLM server. I want Xcode, Simulator, several app projects, Hermes and local models in one development environment. So I looked at what each system can hold and what I can do on one machine, alongside speed.
What systems could that money build?
A GPU alone and a complete Mac are different purchases. A PC also needs a CPU, RAM, storage, power and cooling. My earlier examples added a GPU to roughly ₩2.79M in other parts. Instead of repeating part names, here are the amounts and what they mean.
| Configuration | Recorded amount | How to read it |
|---|---|---|
| My Mac Studio M5 Max 128GB / 1TB | About ₩8.6M | Approximate actual payment · education discount + AppleCare |
| RTX 5090 32GB PC · 64GB system RAM / 1TB SSD | About ₩11.38M | New-parts sum, not a confirmed final purchase quote |
| Same PC with a different 5090 listing | About ₩7.08M | Hypothetical sum using a sold-out GPU price, not purchasable |
| RTX 5080 16GB PC | About ₩5.37M | New-parts example · final quote unconfirmed |
| RTX 3090 24GB PC | About ₩3.84M | Used-GPU asking price + other new parts · transaction/warranty unconfirmed |
| DGX Spark 128GB / 4TB | Domestic listing about ₩10.35M / import listing about ₩8.99M | Stock/final purchase price unverified · import excludes duties/VAT |
Prices recorded on 2026-10-10. PC examples assume Linux and self-assembly, without a final quote including paid OS, assembly or shipping. Spark has 4TB; my Mac has 1TB and AppleCare. These are different packages. Sources are at the end.
The premium ₩16M-class 5090 prebuilt I initially found does not represent typical PC pricing. A sold-out card also cannot establish that ₩8.6M buys a working build today. I have not secured a purchasable complete 5090 quote within my budget. A 5080 or used 3090 could mean spending less, but the next question is whether the models fit their VRAM.
128GB unified memory vs 32GB VRAM
Mac and Spark share 128GB between CPU and GPU. A 5090 has 32GB dedicated VRAM, with system RAM separate. Adding PC RAM does not enlarge GPU VRAM.
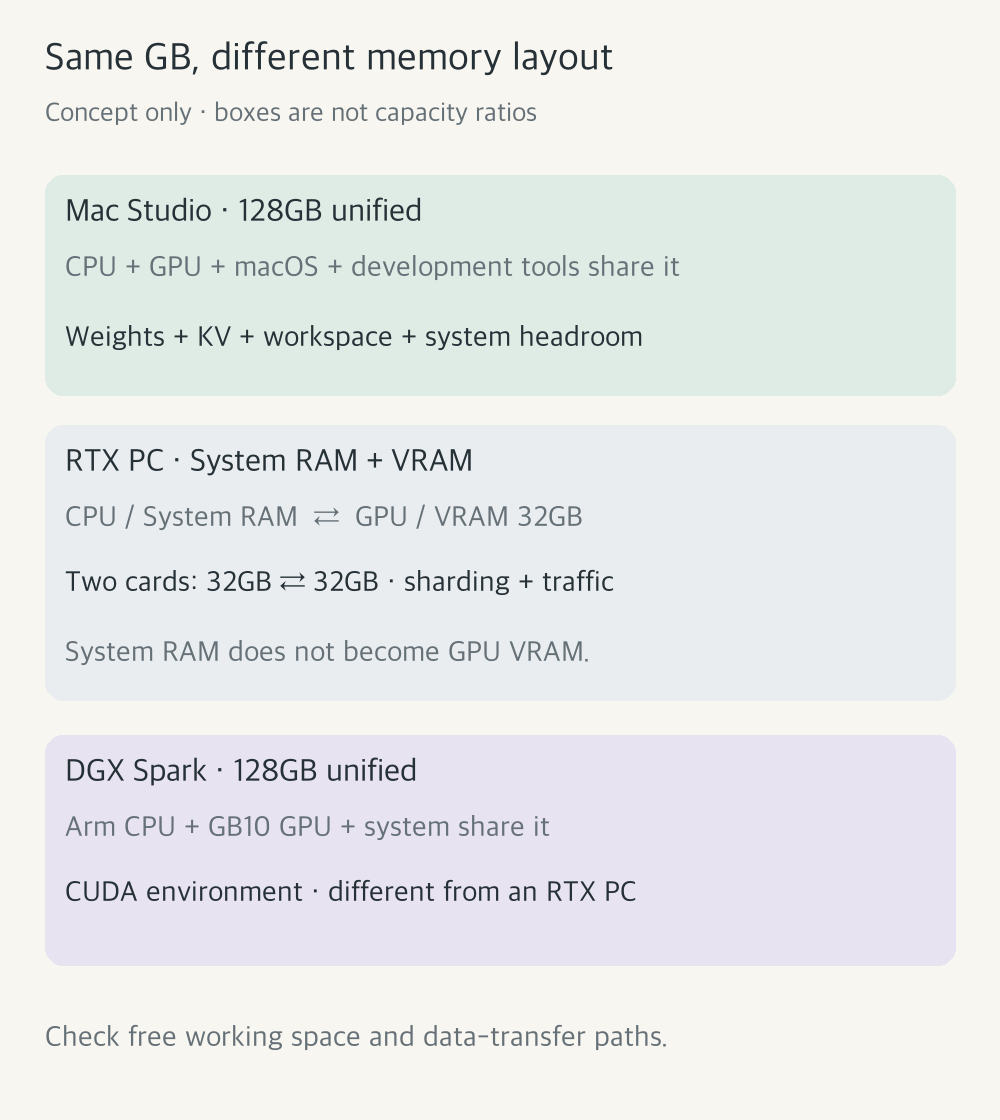
Capacity is room to hold work; bandwidth is how quickly data can move. Separating them helps explain Spark’s appeal and why the 5090 is interesting for fast, smaller models.
| Manufacturer specification | Memory structure | Memory bandwidth (GB/s) |
|---|---|---|
| Mac Studio M5 Max · 40-core GPU | 128GB unified-memory configuration | 614 |
| RTX 5090 | 32GB dedicated VRAM | 1,792 |
| DGX Spark | 128GB unified system memory | 273 |
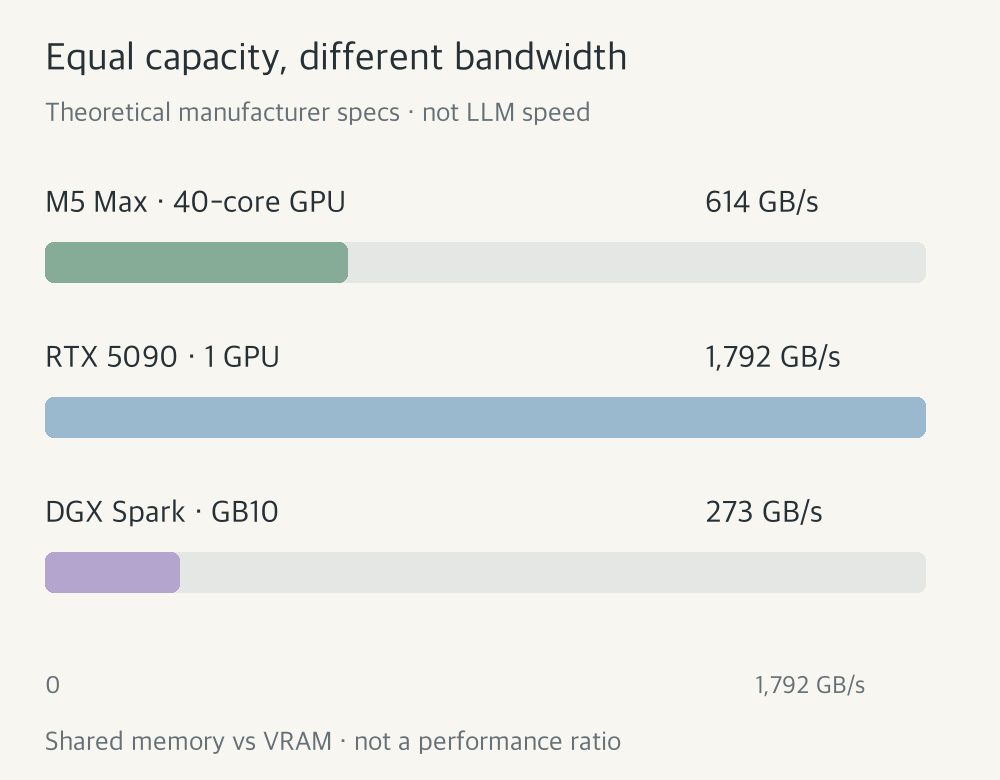
Repeated weight reads can matter during small-batch Decode. Bandwidth ratios are not token-speed ratios: architecture, kernels, caches and compute matter too. The Prefill/Decode distinction in EP01 returns here.
What about the models I want to load?
| Model / workload | Mac Studio 128GB | RTX 5090 32GB PC | DGX Spark 128GB |
|---|---|---|---|
| 20–30B Q4 LLM | Likely capacity fit · count development tools too | Likely capacity fit · check headroom for long context | Likely capacity fit · check runtime |
| 70–100GB of weights alone | Check OS, KV and buffer headroom | Exceeds single VRAM · offload/partitioning and enough system RAM needed | Check OS, KV and buffers · verify Arm runtime |
| Large MoE | Total expert weights determine resident capacity | Small active parameter count does not ensure full weights fit VRAM | Check total weights and runtime support |
| Long context / multiple sessions | KV and workspace compete for shared memory | KV and buffers consume VRAM | KV and workspace compete for shared memory |
20–30B at four bits gives roughly 10–15GB from weight-bit arithmetic alone. Actual files include quantization metadata; execution adds KV cache and buffers. This is not a measured requirement for a specific model. Count the whole budget, as in EP02. Fitting in memory and running at a useful speed are separate questions.
A small active parameter count in MoE does not mean all experts occupy little memory. Two 5090s provide 64GB in aggregate, but not automatically one contiguous pool. Without NVLink, a supported runtime must partition the model and communicate between GPUs. Using EP04’s expert streaming adds SSD read costs to the capacity discussion.
How fast is it? — Prefill and Decode
Capacity does not tell me how long I will wait. I brought back the published llama.cpp results: pp512 processes 512 input tokens; tg128 generates 128 tokens.
Published LLM benchmarks · two stages, small model
Llama 2 7B Q4_0 · GPU offload 99. Independent community submissions, not controlled for hosts, drivers, runtime, file hashes or power. NVIDIA: CUDA / FA off; Mac: Metal / FA setting unconfirmed. pp512: 512 input tokens; tg128: 128 generated tokens. Separate zero-origin scales.
Speed references for a small model that fits memory. Not a value ranking accounting for whole-system cost, large-model capacity, Xcode or energy.
Prefill · pp512
0 — 15,000 tokens/s
- RTX 509014,073.41
- RTX 409011,992.70
- RTX 50808,297.36
- RTX 30905,174.69
- RTX A60004,913.93
- M5 Max · MacBook Pro3,347.44
- DGX Spark · 128GB3,062.31
Decode · tg128
0 — 300 tokens/s
- RTX 5090290.02
- RTX 4090186.21
- RTX 5080181.99
- RTX 3090158.16
- RTX A6000138.73
- M5 Max · MacBook Pro119.08
- DGX Spark · 128GB57.21
Mac reference: 16-inch MacBook Pro, M5 Max / 40 GPU cores / 128GB, submitted 2026-06-22. Not my Mac Studio. Cooling, power, runtime and file hashes are unmatched; the shared chip does not establish Studio speed.
| Measured device / backend | Prefill pp512 tok/s | Decode tg128 tok/s | llama.cpp Commit · source |
|---|---|---|---|
| RTX 5090 CUDA · FA off | 14073.41 ± 115.16 | 290.02 ± 1.10 | 8cf6b42@totaldev |
| RTX 4090 CUDA · FA off | 11992.70 ± 107.99 | 186.21 ± 0.13 | 2241453@lhl |
| RTX 5080 CUDA · FA off | 8297.36 ± 9.50 | 181.99 ± 0.42 | 8a4280c@Hedede |
| RTX 3090 CUDA · FA off | 5174.69 ± 21.83 | 158.16 ± 0.21 | c76b420@m18coppola |
| RTX A6000 CUDA · FA off | 4913.93 ± 6.79 | 138.73 ± 2.75 | 4795c91@Hedede |
| M5 Max · MacBook Pro 16″ · 40 GPU cores · 128GB · Metal/BLAS · 6 threads · FA ? | 3347.44 ± 1.53 | 119.08 ± 0.69 | 52b3df0@michaelasper |
| DGX Spark · 128GB CUDA · FA off | 3062.31 ± 11.02 | 57.21 ± 0.06 | 5acd455@ggerganov |
Source and runtime commits
llama.cpp · CUDA scoreboard (no FA) · 2026-10-10
llama.cpp · Apple Silicon · @michaelasper · 2026-06-22 · Checked 2026-10-10
- RTX 5090 ·
8cf6b42· @totaldev - RTX 4090 ·
2241453· @lhl - RTX 5080 ·
8a4280c· @Hedede - RTX 3090 ·
c76b420· @m18coppola - RTX A6000 ·
4795c91· @Hedede - M5 Max · MacBook Pro ·
52b3df0· @michaelasper - DGX Spark · 128GB ·
5acd455· @ggerganov
Curated newer/stronger submissions introduce selection bias. A6000 here means Ampere.
For this small model that fits memory, the 5090’s throughput stands out. The 4090, 5080 and 3090 references also give reasons to consider less expensive cards. Spark has 128GB, yet that capacity does not turn into proportionally faster small-model Decode. Holding a large model and running a small model quickly are different strengths.
I also lack matched three-system results for large MoE or 70–100GB weights, so I have not filled those gaps with estimated speeds.
Long-input Prefill, Decode and time to first token are different metrics. EP03’s acceleration changes the balance again through verification cost and accepted length. Once the machine arrives, I want to start with short and long answers using my own models.
Which system fits my work?
I move between Cookly, KnitLens, Delsa, Sobok and Sound Journey. On my M1 iMac with 8GB RAM and 256GB storage, IDEs, Xcode and Simulator make both resources tight. A Samsung T7 1TB helps with storage, but putting simulators on it has been slow and inconvenient. That is where EP00 started.
An RTX PC or Spark can take the AI workload. Xcode and Simulator would still run on the Mac, though. Buying a GPU server does not upgrade the 8GB iMac’s development environment. Windows/Linux PCs and Spark cannot directly replace Xcode, so my comparison becomes one Mac Studio versus a development Mac plus an AI server.
CUDA is appealing for image/video generation and LoRA. ComfyUI also supports Apple Silicon, but the specific models, custom nodes and training backends need checking. Spark’s CUDA and large shared memory likewise do not guarantee every RTX workflow works unchanged on Arm Linux.
My plan is to use Hermes and a medium LLM frequently, then switch to a larger model or vision, speech or image models when needed. I do not intend to keep everything resident. Changing budget, purpose and model size helps expose the trade-offs.
Where would I start for my workload?
A workload checklist, not a performance predictor or purchase ranking. Prices checked 2026-10-10. Sold-out or unverified quotes are not purchasable candidates.
- Configuration to investigate
- Compare Mac Studio with a Mac plus a separate GPU server
- Advantage
- A Mac can host Xcode and local AI in the same development environment.
- Constraint
- CUDA-only jobs may need another environment. A PC alone cannot replace Xcode. For 20–30B Q4, roughly 10–15GB is only weight-bit arithmetic. Count actual files, KV and buffers; check headroom particularly on 16GB GPUs.
- Check next
- Check memory with development tools, existing Mac condition and two-machine costs.
- Price and stock status
- My Mac was about ₩8.6M; new-5080 parts about ₩5.37M, opened/unused-4090 parts about ₩9.18M. Spark import listing: ₩8.99M before import duties/VAT, final purchase price unverified. Eligibility, stock and final quotes need checking. The sold-out-GPU ₩7.08M 5090 is excluded from purchasable candidates.
This is not a quotation tool that automatically picks purchasable complete systems. I am starting with the development environment plus memory capacity, then revisiting a Mac plus GPU server if CUDA work becomes important. OpenCode Go and Codex will remain part of the setup; one local model does not need to carry my entire budget.
Why I chose the Mac Studio
I did not buy it after proving it was the fastest LLM machine. I wanted a better app-development environment and enough memory to experiment with local AI together. It is an attempt to fix two recurring frustrations on my 8GB iMac.
If a CUDA-only video workflow or KnitLens training hits a wall on Mac, an NVIDIA server or cloud service may fit better. For development tools beside agents and models, with occasional large-model experiments, macOS plus a large shared space appeals to me. Spark remains an interesting large-model server candidate, but I would still need a separate development Mac.
I also want to measure idle power for always-on Hermes and energy per completed workload. GPU TGP or adapter capacity is not whole-system electricity use. Actual power and usage time are needed before operating-cost conclusions.
I will judge the ₩8.6M decision through development waits, model switching and the image/video workflows I actually use. After delivery, I want to return with “Was the ₩8.6M choice worth it?”
First, the machine has to arrive.
References
Checked October 10, 2026. Mac prices are approximate amounts from my purchase. Retail amounts refer to particular observed configurations, not market minimums/averages or confirmed purchase quotes.
-
Specifications/development: Apple Mac Studio, RTX 5090, DGX Spark, Xcode requirements.
-
Published performance/execution: llama.cpp CUDA submissions, Apple Silicon submissions, ComfyUI, MLX, Spark Arm porting guide, multi-GPU inference.
-
Pricing: 5090 card, sold-out conditional card example, specific premium prebuilt, 5080 card, 3090 used asking price, Spark Korean listing, Spark import listing. PC totals add the roughly ₩2.79M non-GPU parts observed at the time.
-
Memory bandwidth: Apple Studio specifications, NVIDIA Blackwell architecture, DGX Spark specifications. Checked 2026-10-10.
Comments & likes
No account needed. Your nickname and comment will be public. Comments appear after review.